【第210期】RLSP:Reinforcement Learning via Self-Play
Seventy3:借助NotebookLM的能力进行论文解读,专注人工智能、大模型、机器人算法方向,让大家跟着AI一起进步。
进群添加小助手微信:seventy3_podcast
备注:小宇宙
今天的主题是:
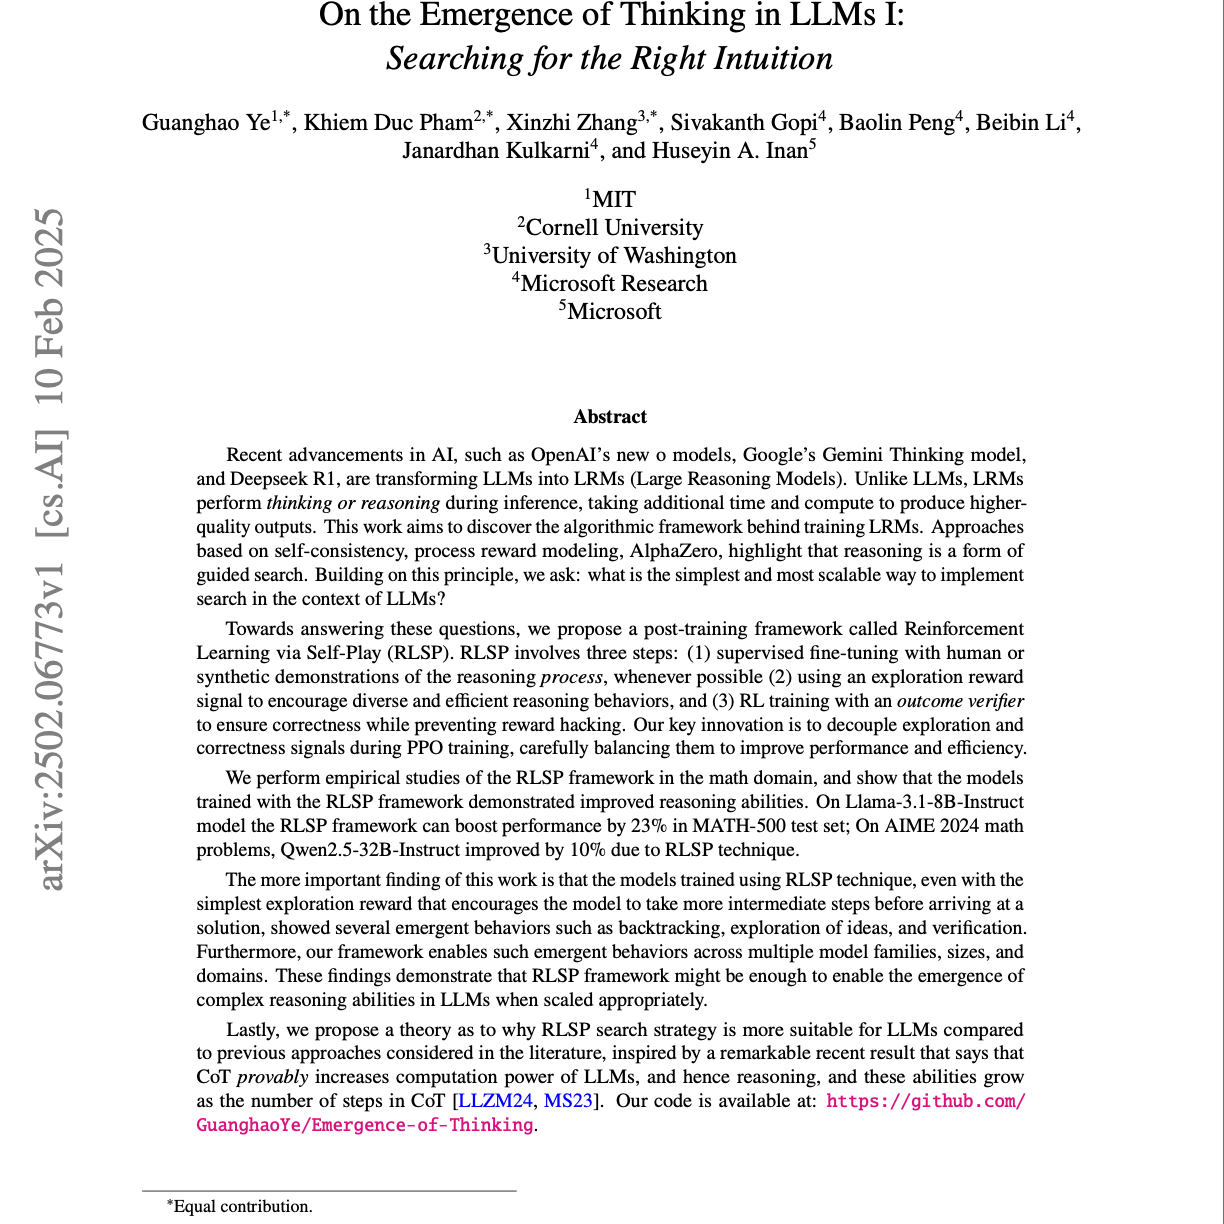
On the Emergence of Thinking in LLMs I: Searching for the Right Intuition
Summary
The provided research explores how large language models (LLMs) can be transformed into more capable reasoning agents, termed large reasoning models (LRMs), by enabling a "thinking" process during inference. It introduces Reinforcement Learning via Self-Play (RLSP), a post-training framework that encourages guided search in LLMs through supervised fine-tuning on reasoning demonstrations, an exploration reward…
The skinny
The skinny isn't ready yet — notes appear once the transcript is processed.