Latest / learning with yacine show
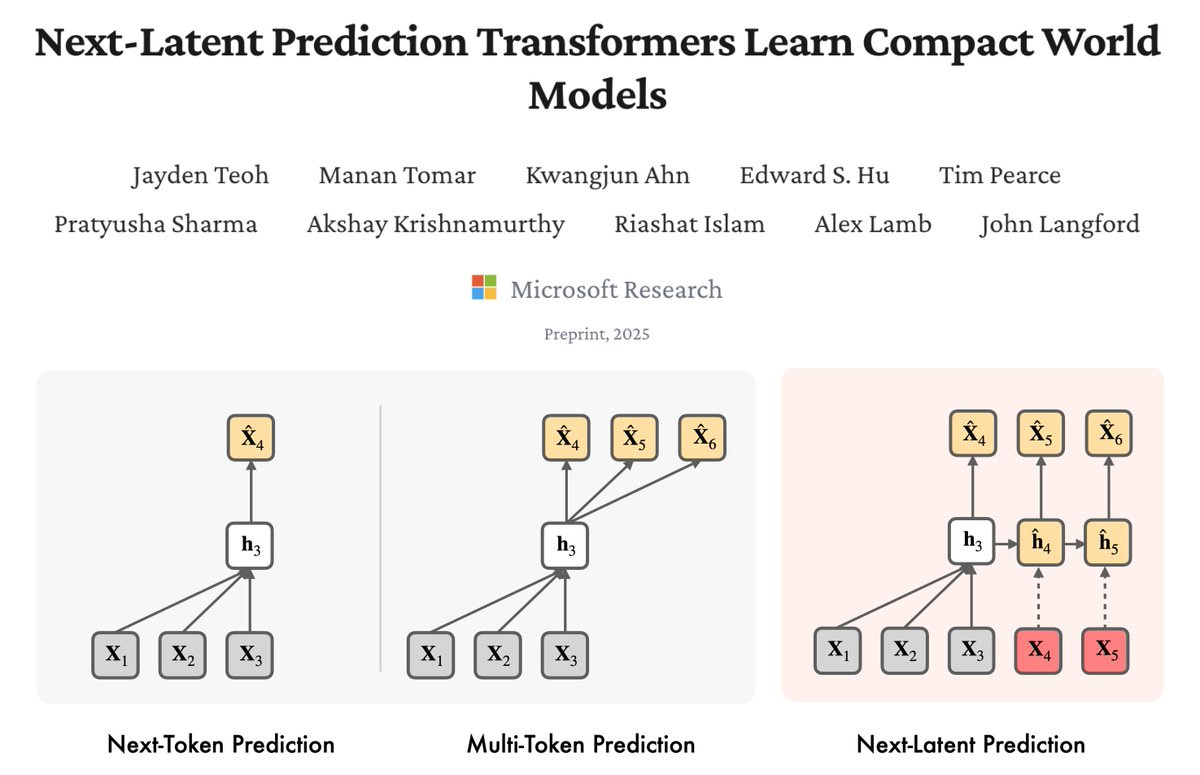
Next-Latent Prediction Transformers Learn World Models feat. Jayden Teoh from MIT
it’s very interesting to see where next-token transformers still fall short (like the path-star graph problems) while crushing problems that look even more daunting.I had the pleasure of chatting with jayden teoh from MIT who walks us through next-latent prediction (NextLat), a simple fix in the training objective he worked on when he was still an undergrad!the change is super tiny: -> bolt a small MLP onto a GPT and make it predict the transformer’s own next hidden state. to pull that off, the internal representation of the transformer needs to become a belief state, a compact summary of…
The skinny
The skinny isn't ready yet — notes appear once the transcript is processed.