222-InterPLM: Interpretable Protein Language Models
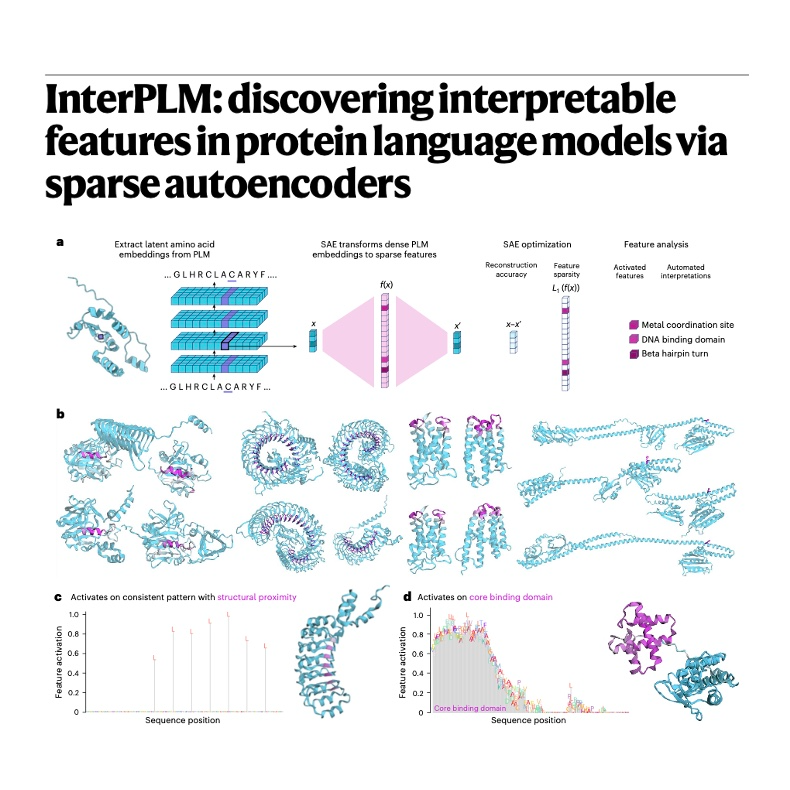
The paper introduces "InterPLM," a systematic framework for interpreting protein language models (PLMs) using sparse autoencoders (SAEs). This method successfully extracts thousands of interpretable features from PLMs like ESM-2, revealing biological concepts such as binding sites and functional domains that are stored in superposition within the model's neurons. The research demonstrates that SAE features show significantly stronger alignment with known biological annotations than individual neurons and that larger PLMs capture a broader range of concepts. Furthermore, the framework…
The skinny
The skinny isn't ready yet — notes appear once the transcript is processed.